|
My research interests revolve around unified generation and understanding and controllable vision generation(image&video). If you are interested in my work, please feel free to reach out for discussions or collaborations! |
|
|
|
|
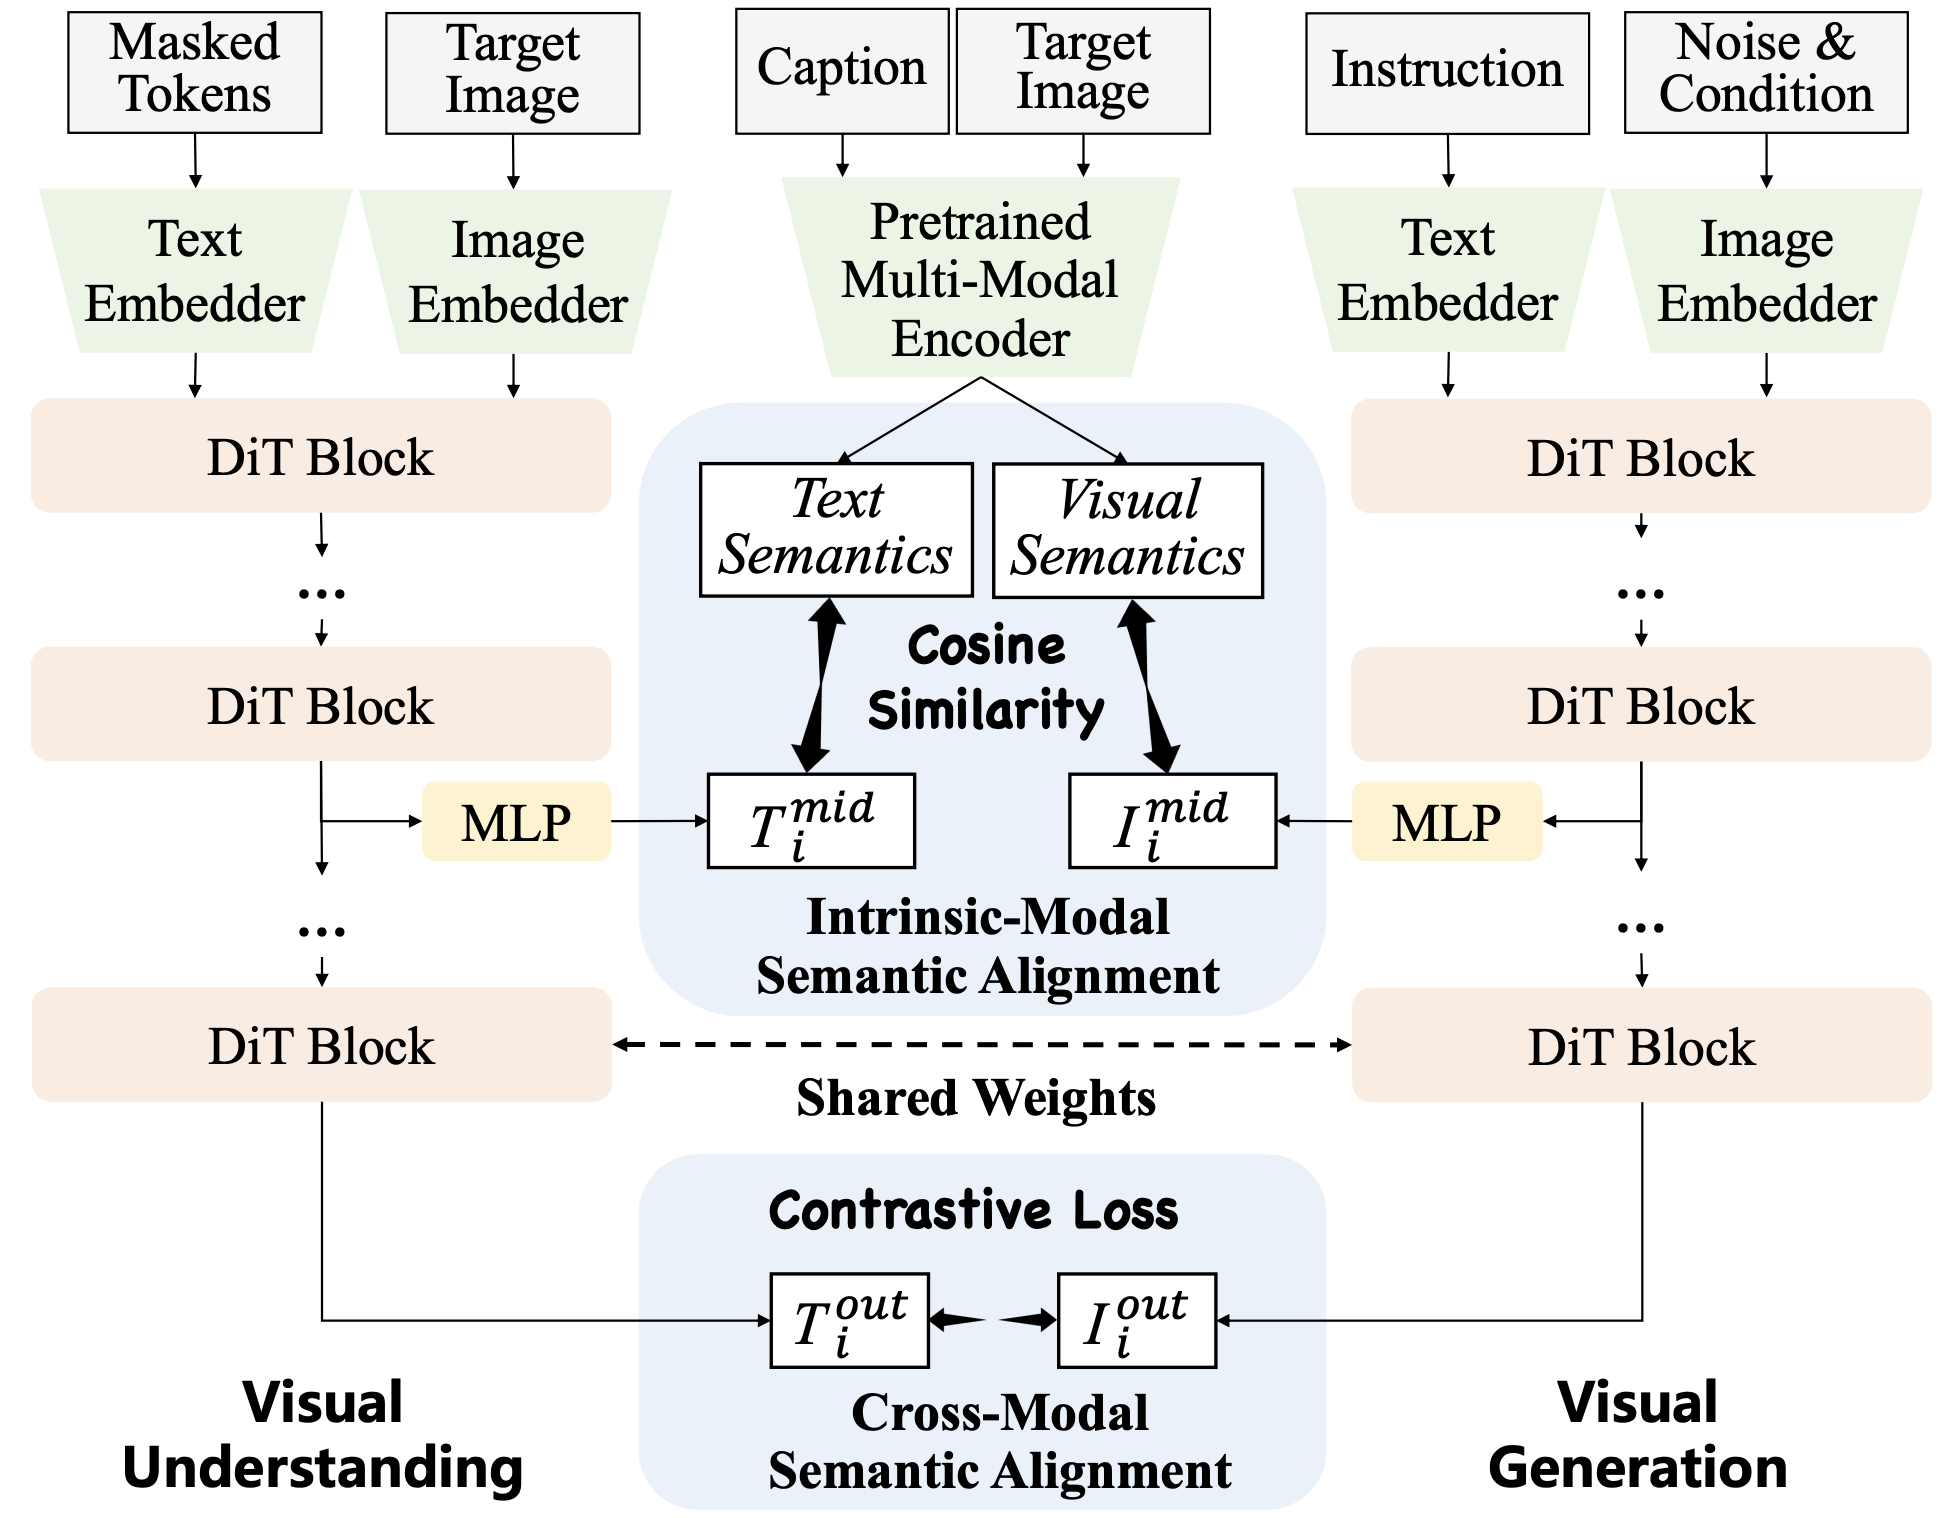
Xinyang Song, Libin Wang, Weining Wang, Shaozhen Liu, Dandan Zheng, Jingdong Chen, Qi Li, Zhenan Sun AAAI, 2026 [paper] [code] UniAlignment, a novel dual-branch diffusion-based framework, enables unified image generation, understanding, manipulation and perception through two forms of semantic alignment: intra-modal semantic alignment and inter-modal semantic alignment. |
|
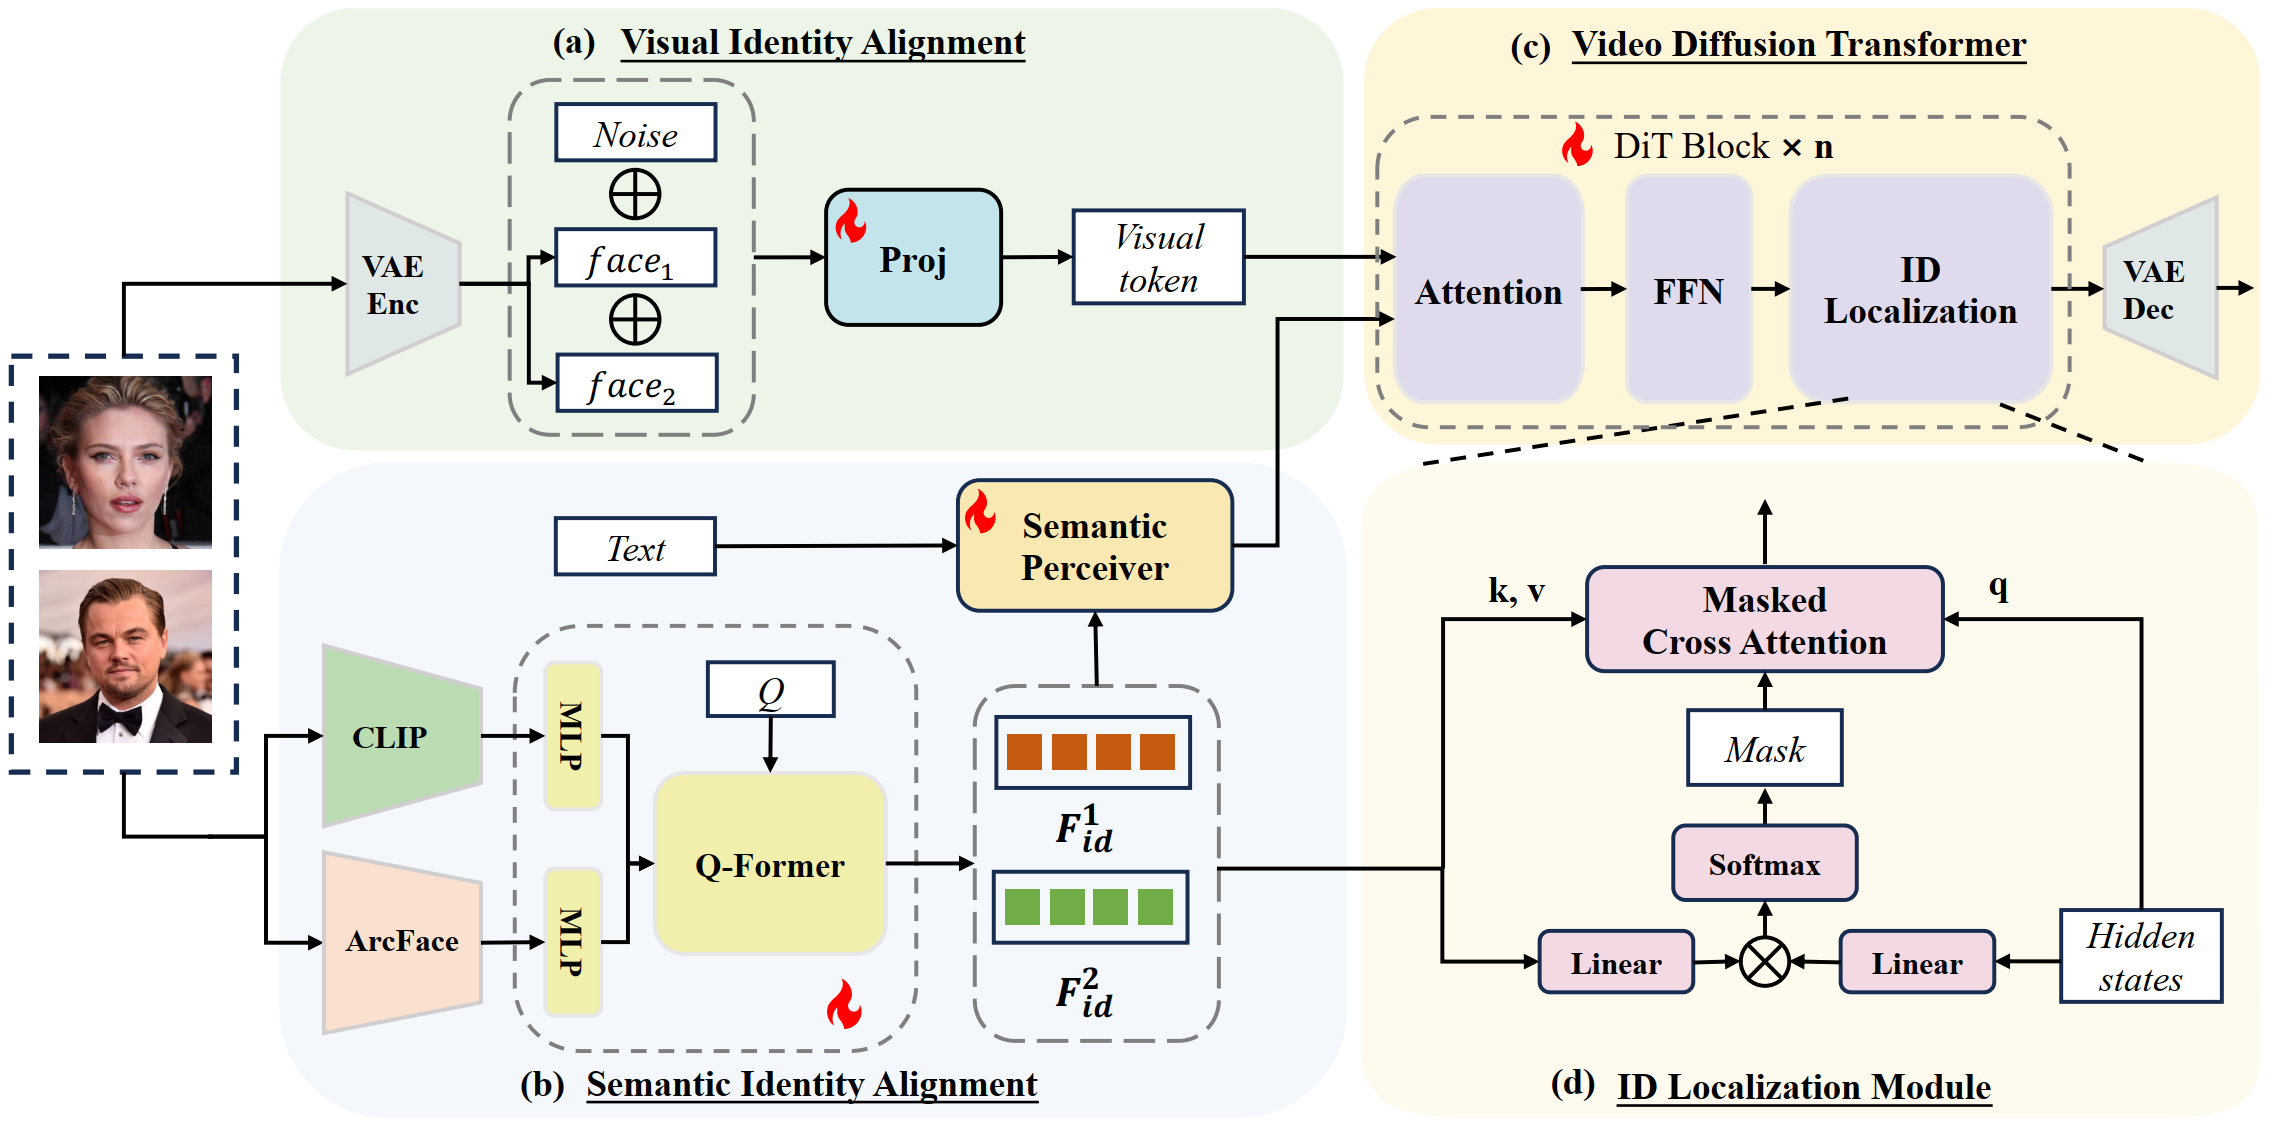
Xinyang Song, Libin Wang, Jianxin Sun, Qi Li, Dandan Zheng, Jingdong Chen, Zhenan Sun IEEE Transactions on Multimedia (TMM), 2025 [paper] GroupVideo, a novel video dit framework that leverages multiple individual photographs to generate identity-customized video. |
|
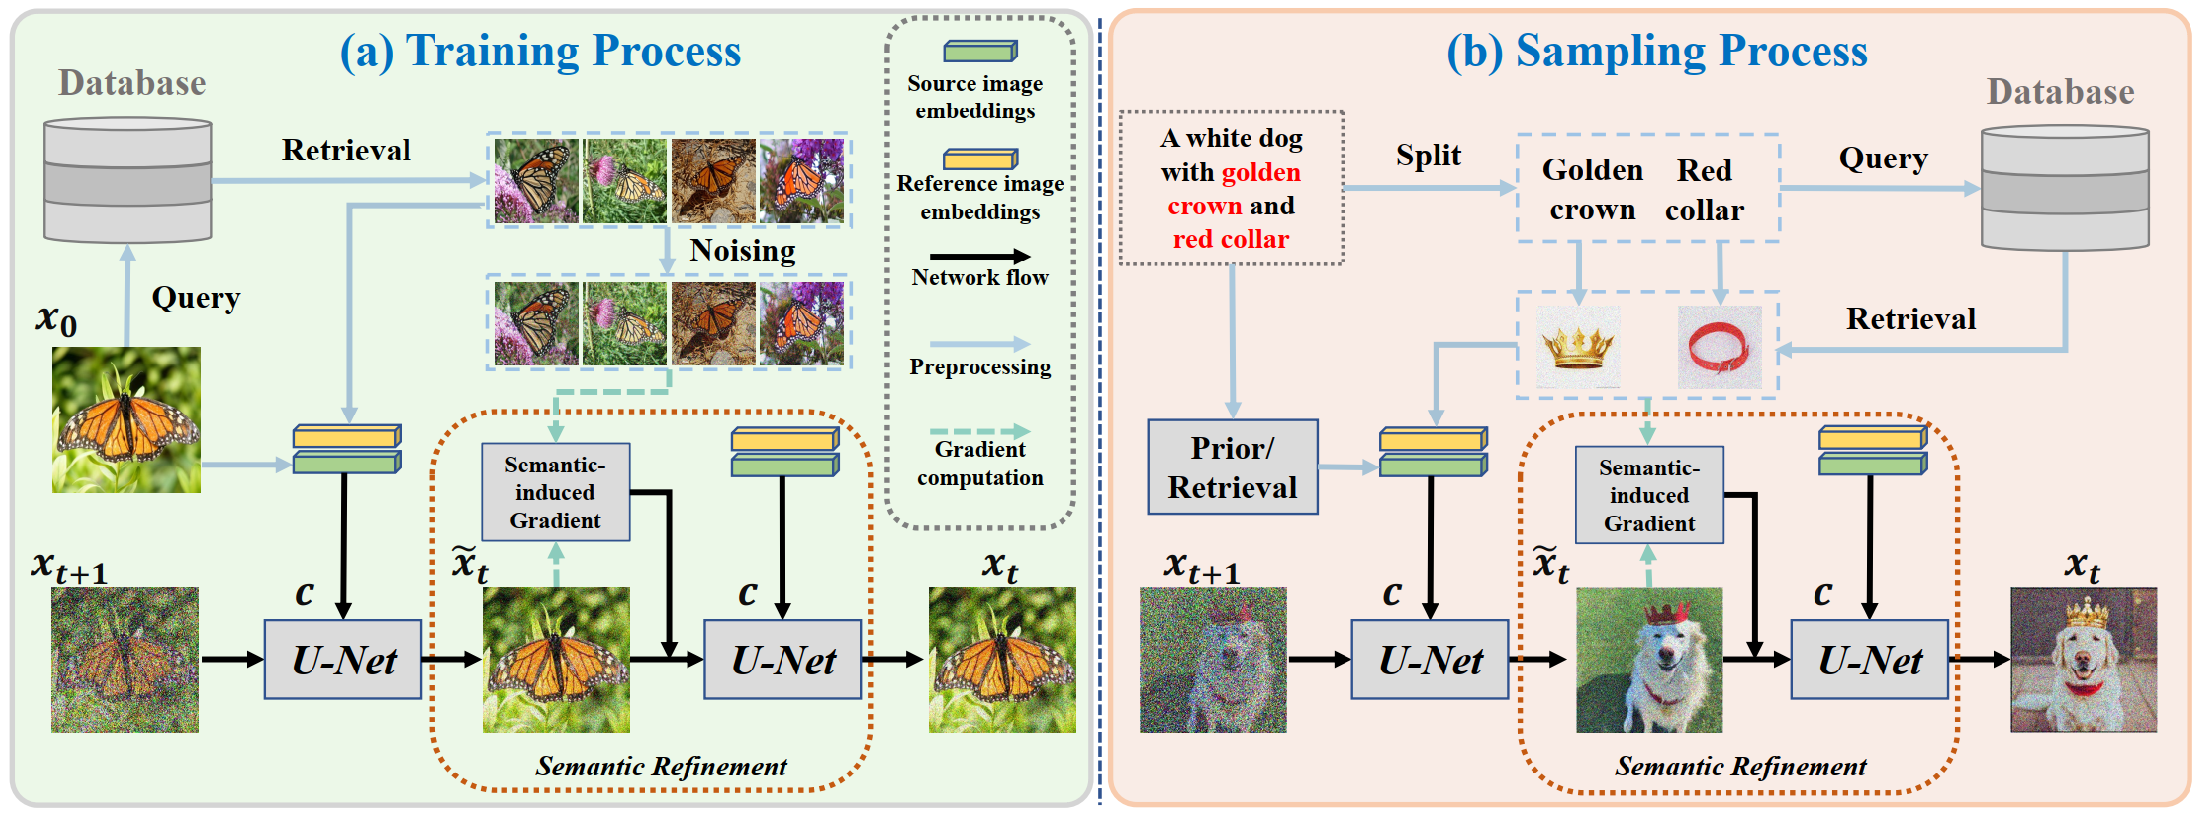
Xinyang Song*, Jianxin Sun*, Yingya Zhang, Libin Wang, Qi Li, Zhenan Sun ICASSP, 2026 (Oral) [paper] SeReDiff, a fine-grained text-to-image generation framework based on semantic refinement. |
|
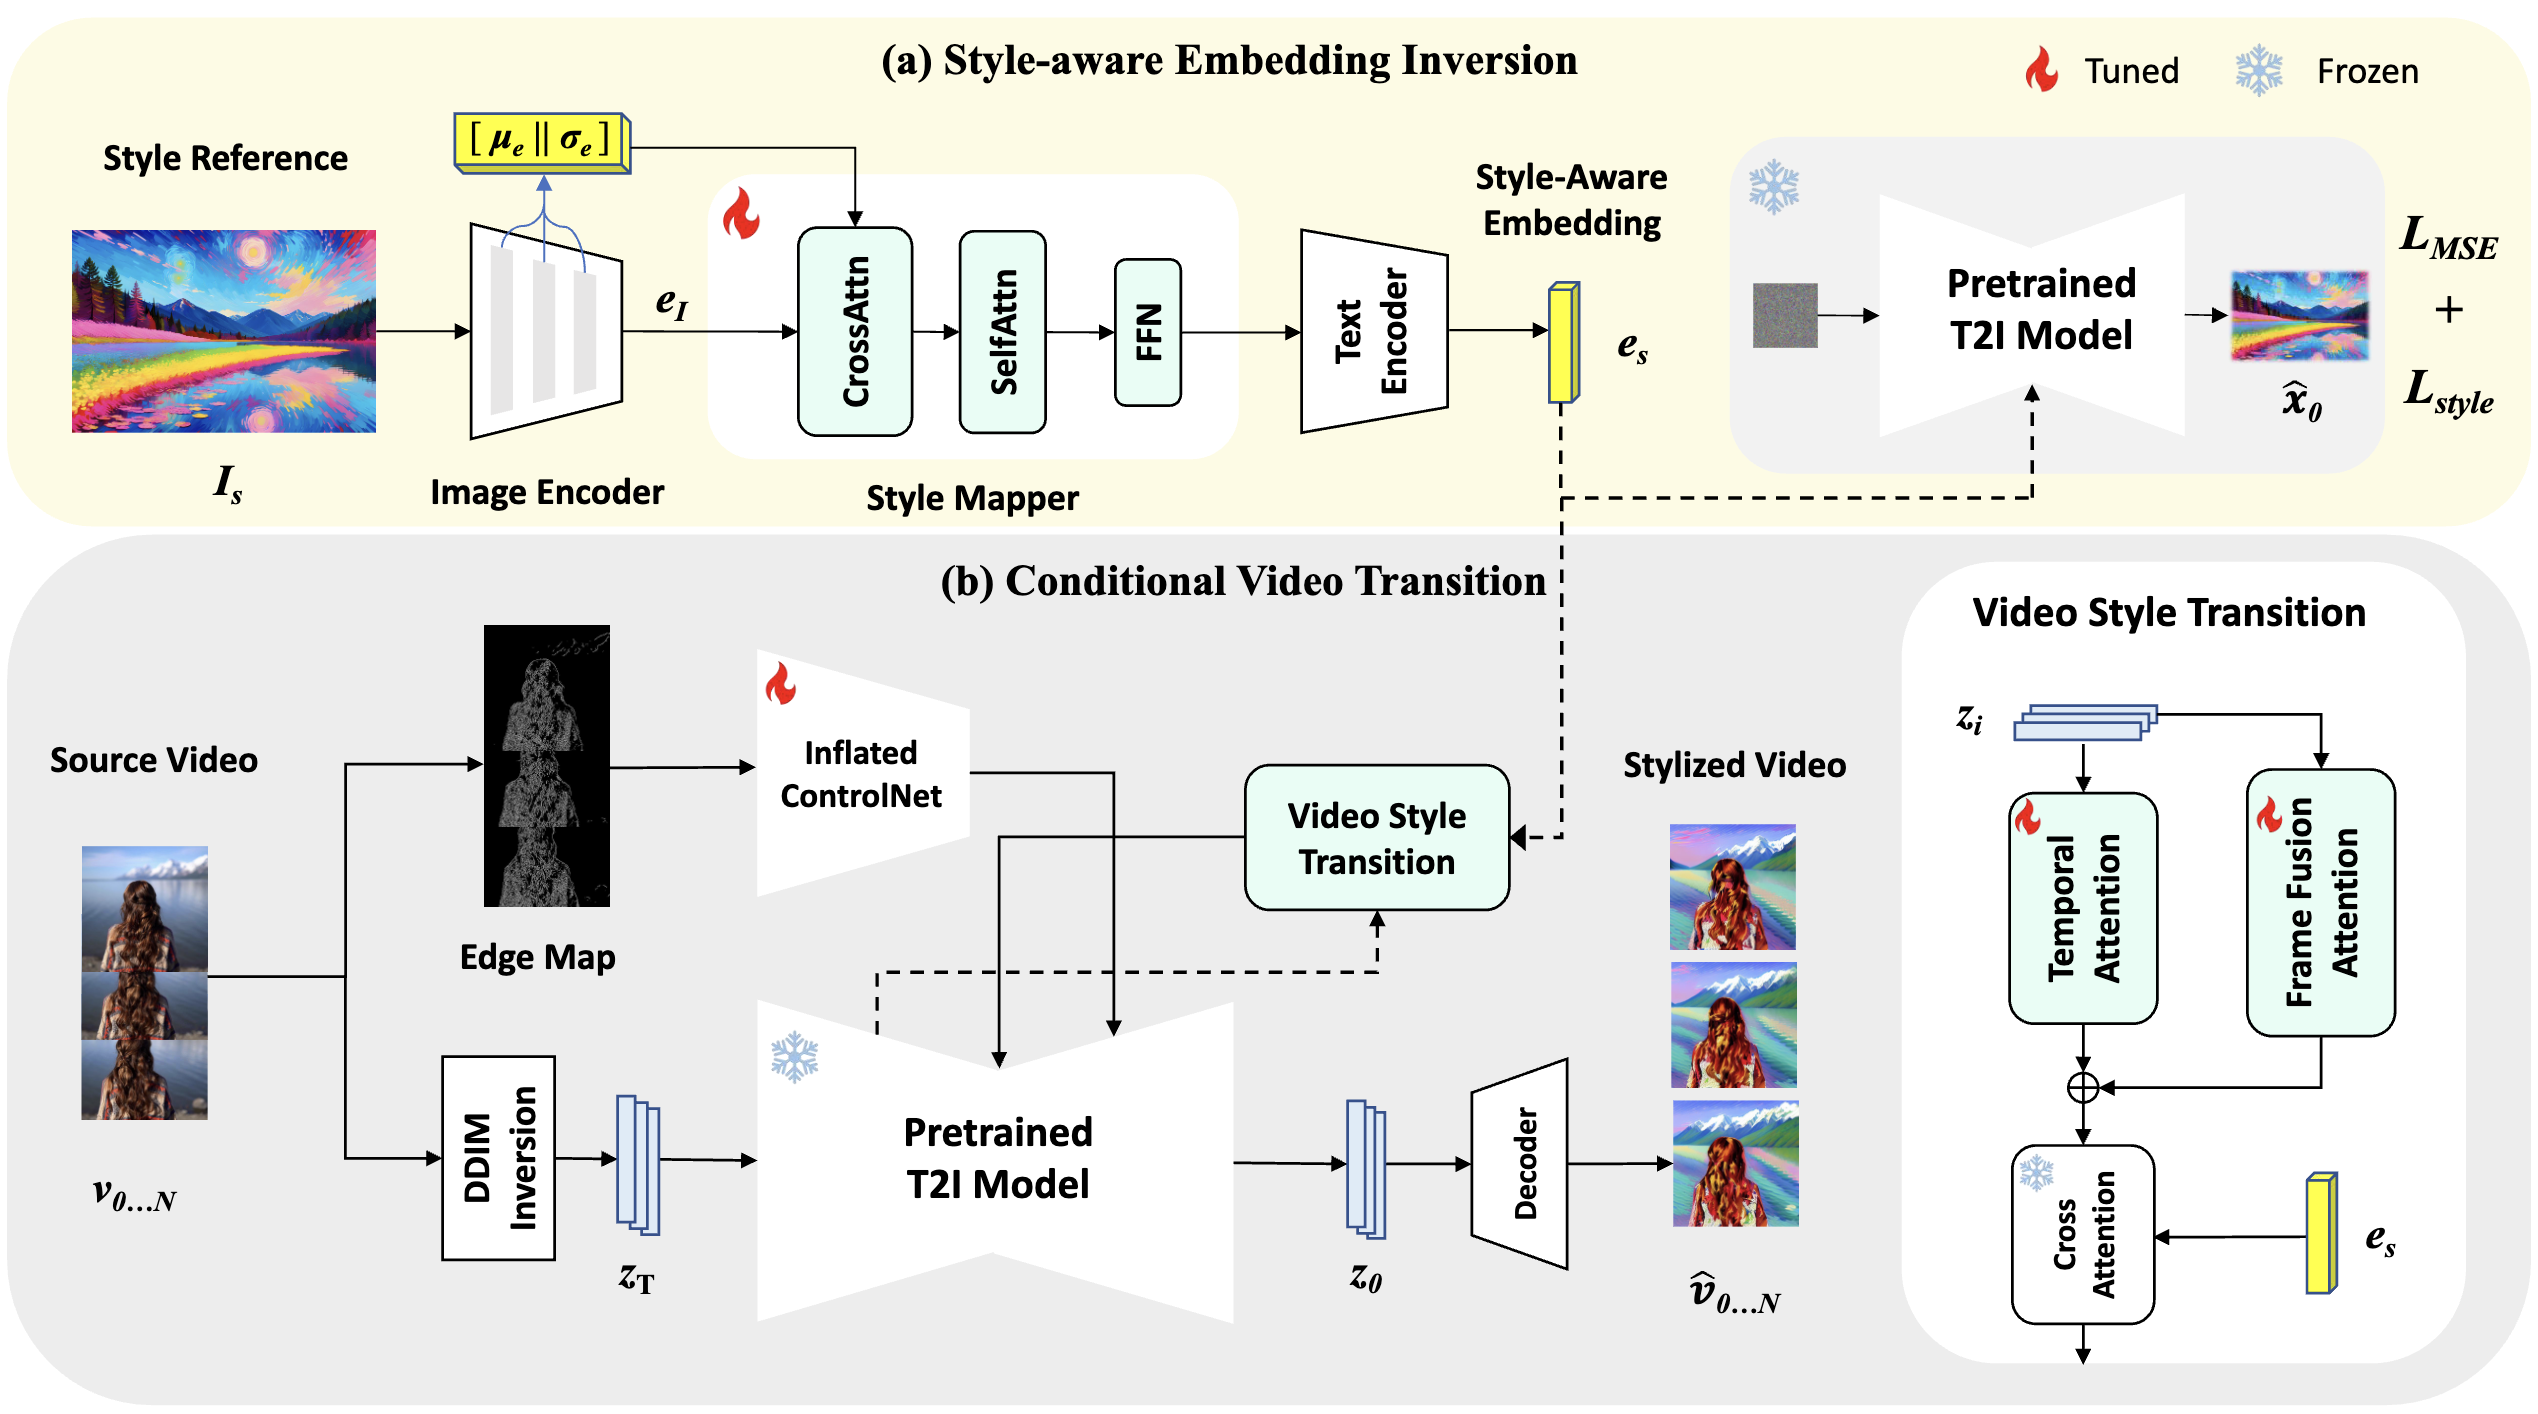
Xinyang Song, Xi Yong, Qi Li, Jianxin Sun, Yunfan Liu, Zhenan Sun Machine Intelligence Research (MIR), 2025 StyleVideo, a one-shot method that realizes image-guided video style transfer by leveraging diffusion models. |
|
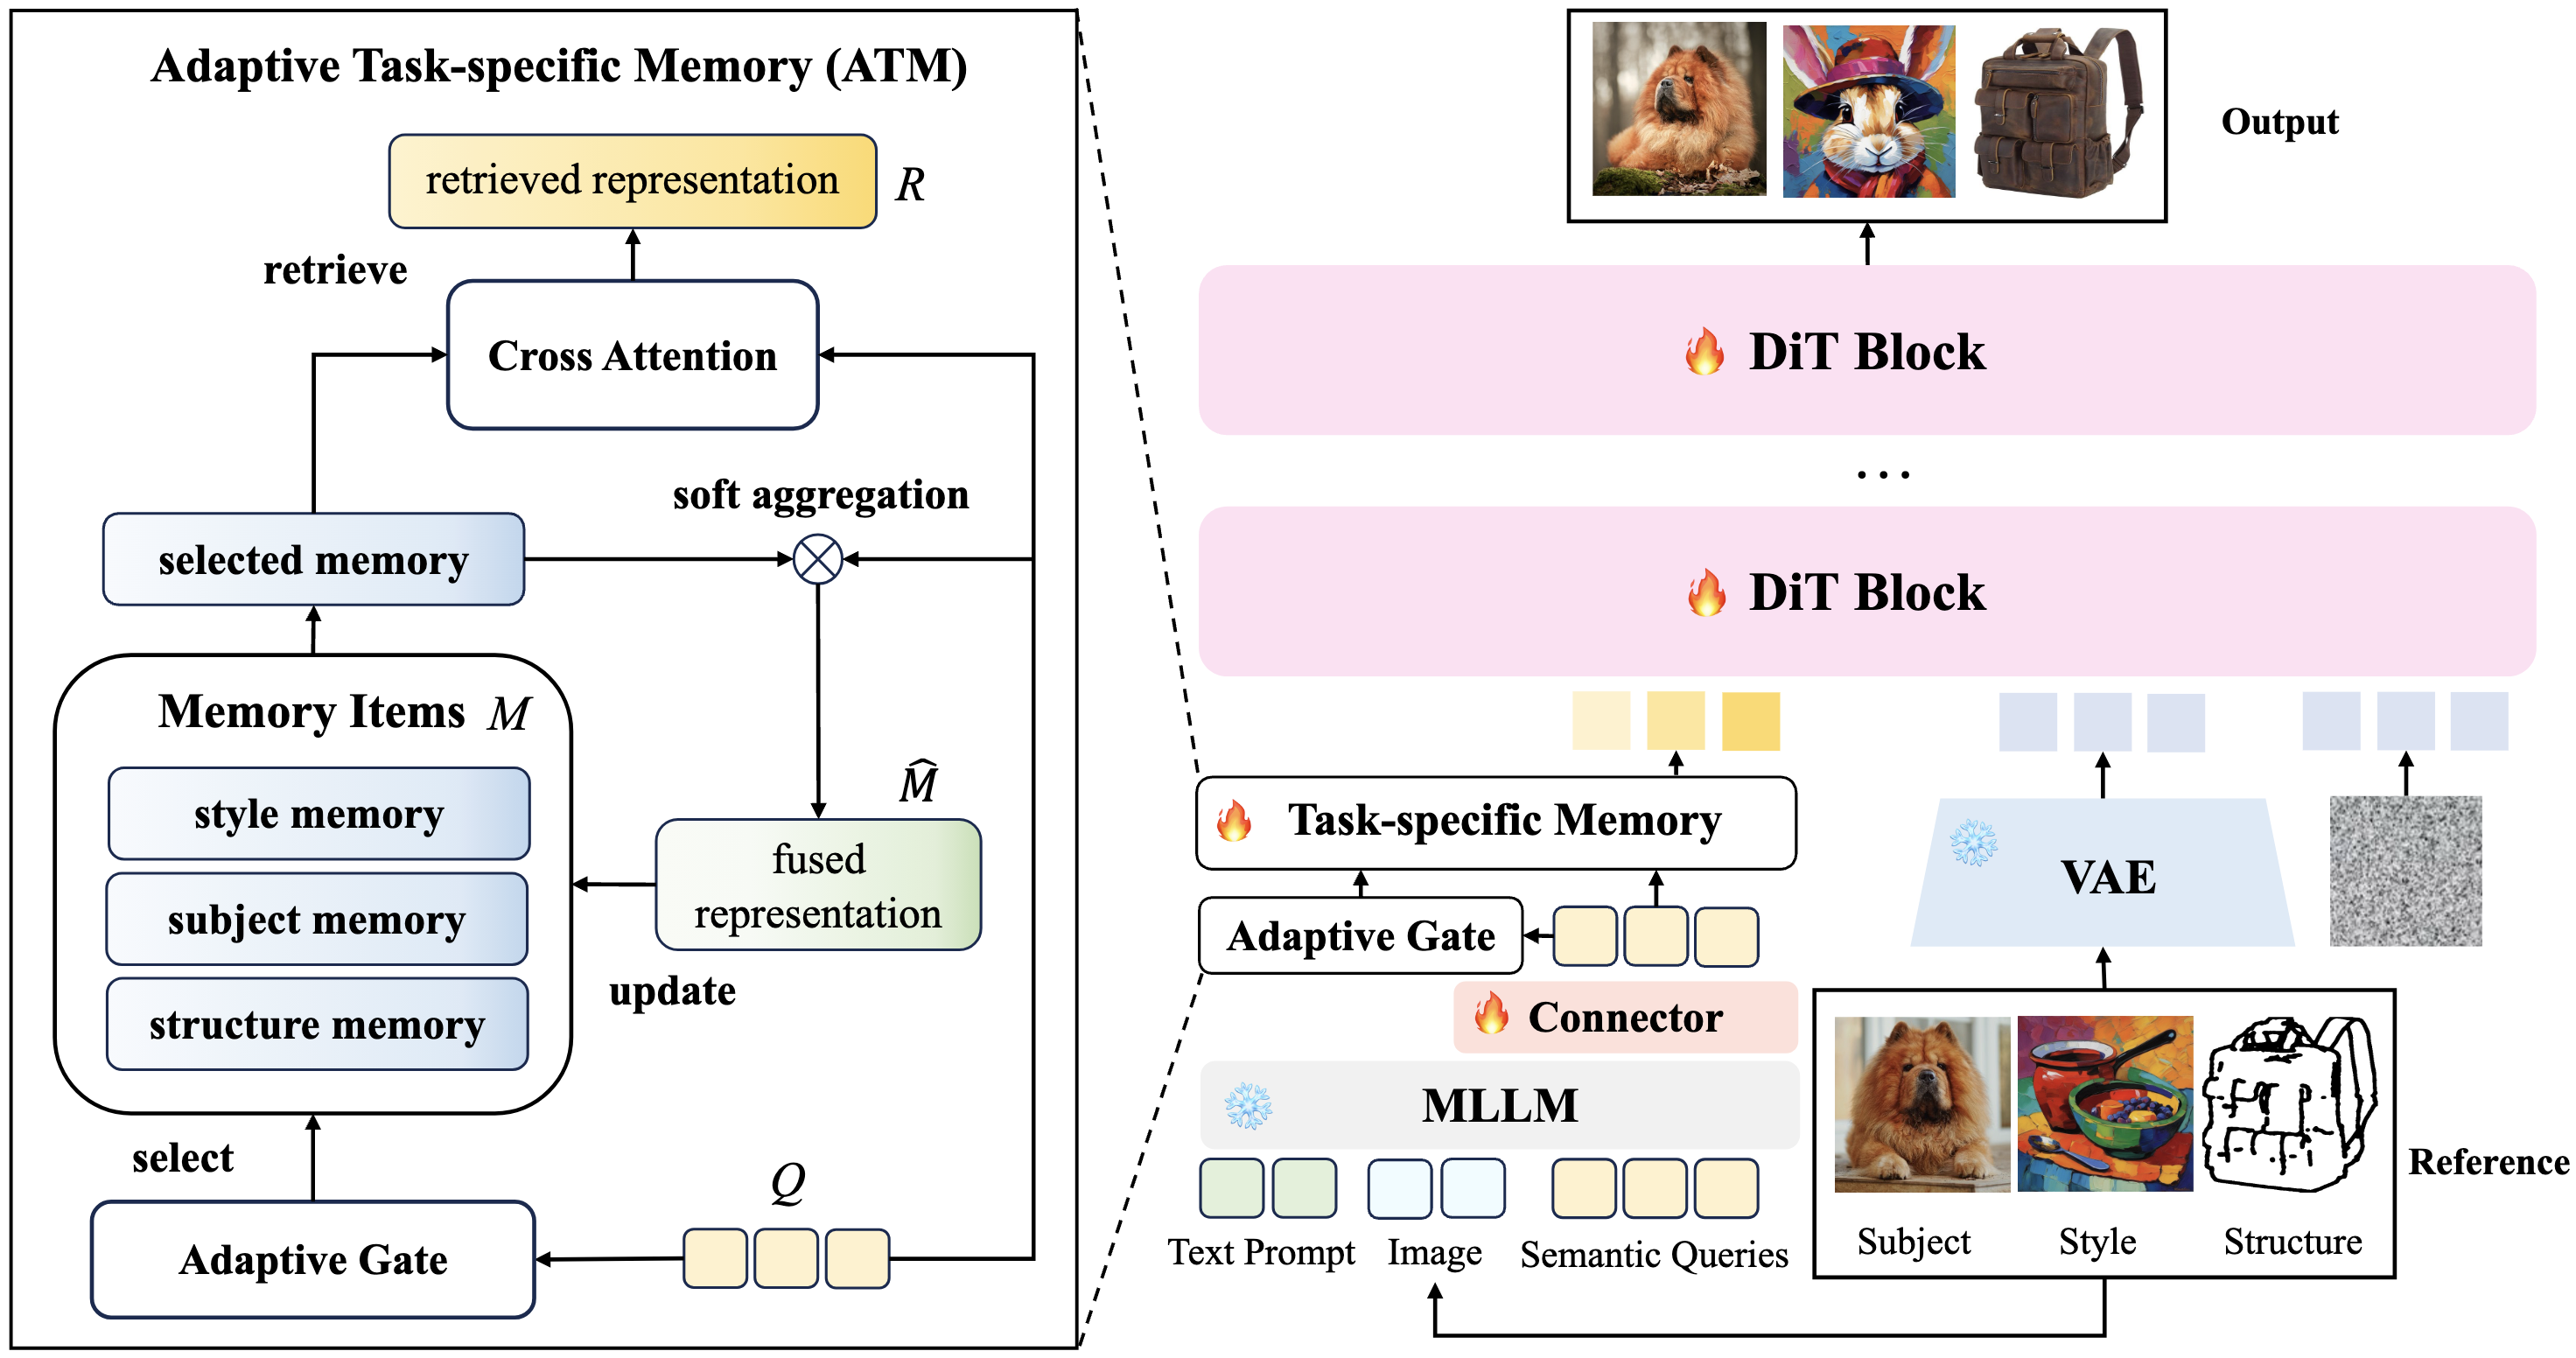
Xinyang Song, Libin Wang, Weining Wang, Zhiwei Li, Jianxin Sun, Dandan Zheng, Jingdong Chen, Qi Li, Zhenan Sun arxiv, 2025 [paper] 3SGen, a taskaware unified framework that performs subject-driven, style-driven and structure-driven conditioning modes within a single model. |
|
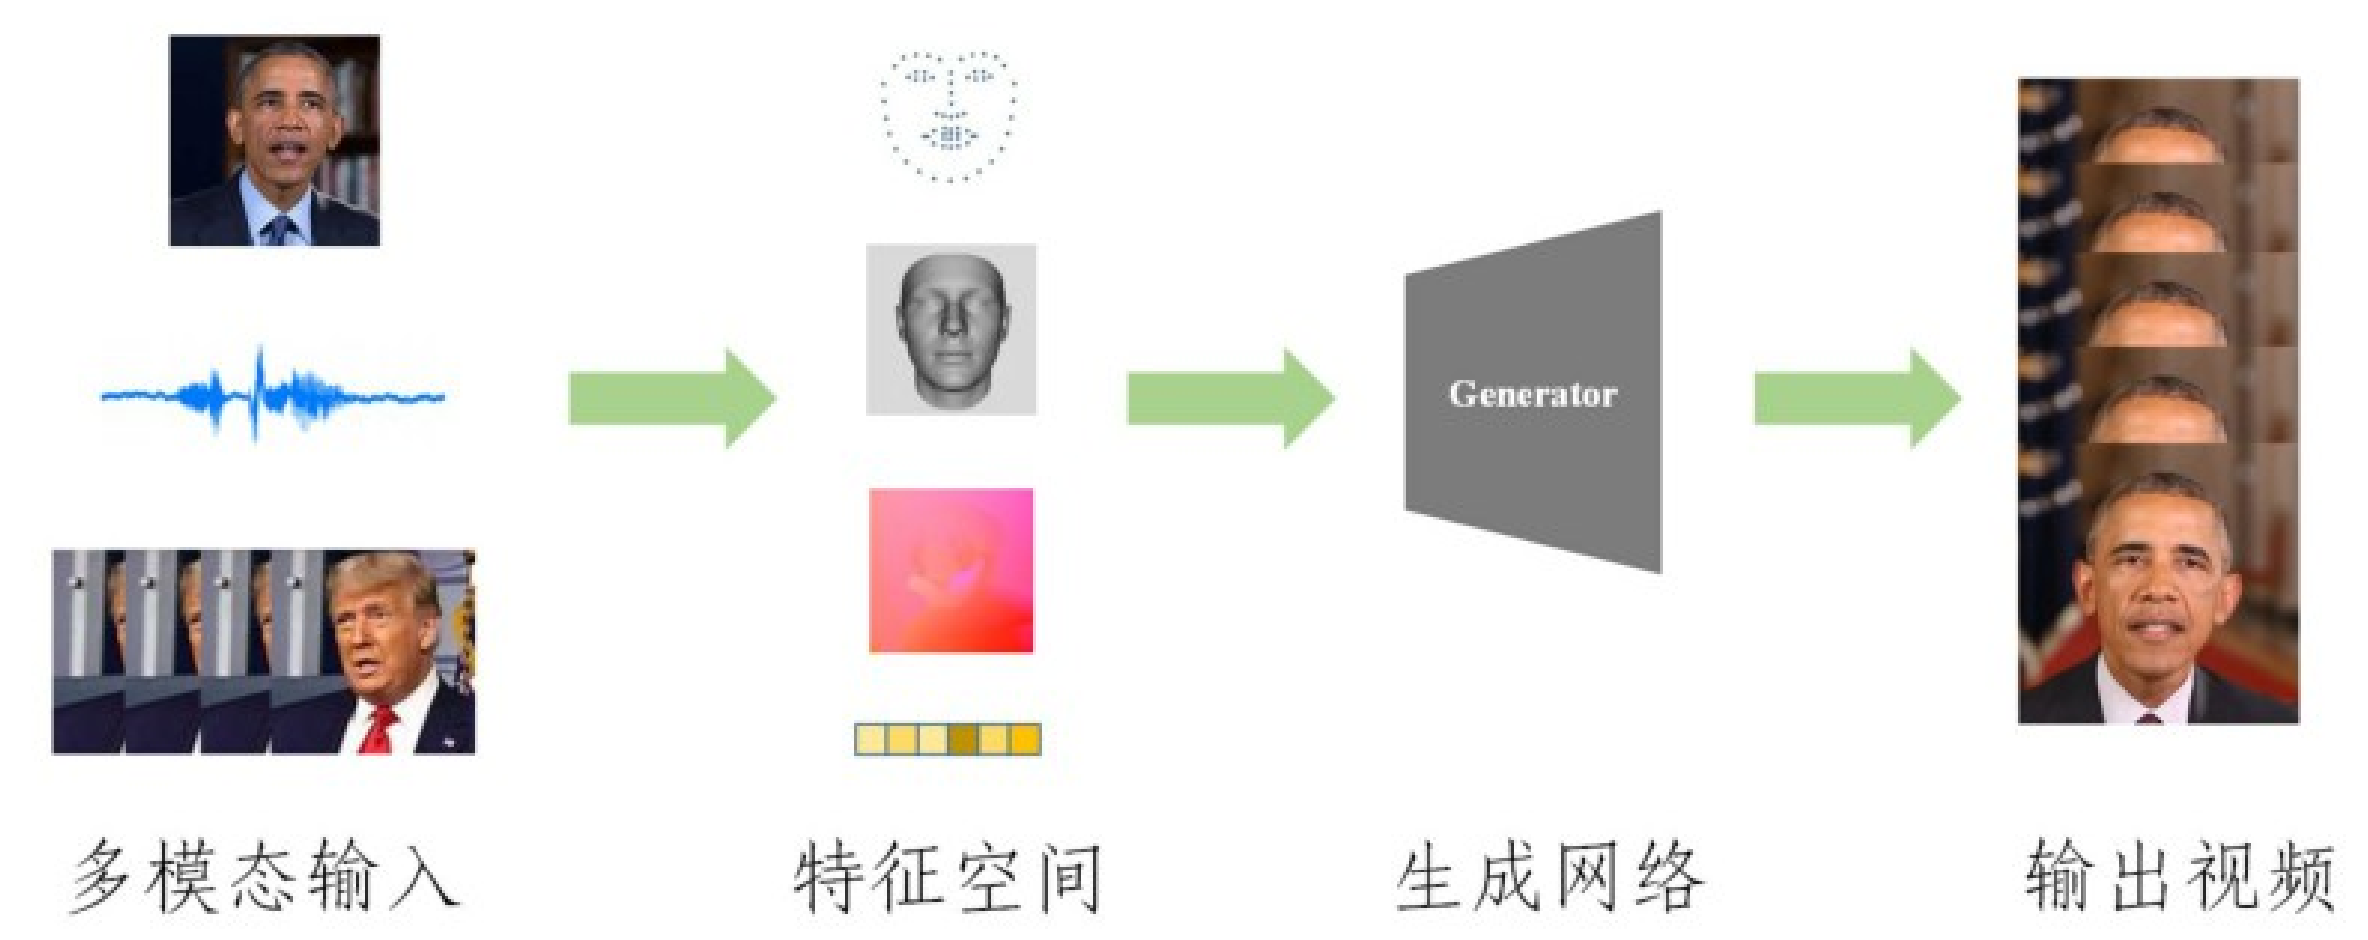
Xinyang Song, Zhiyuan Yan, Muyi Sun, Linlin Dai, Qi Li, Zhenan Sun Computer Science, 2023 A Chinese survey on the current status and development trends of talking face generation research. |
|
|
|
|